AI/ML Infrastructure Engineer

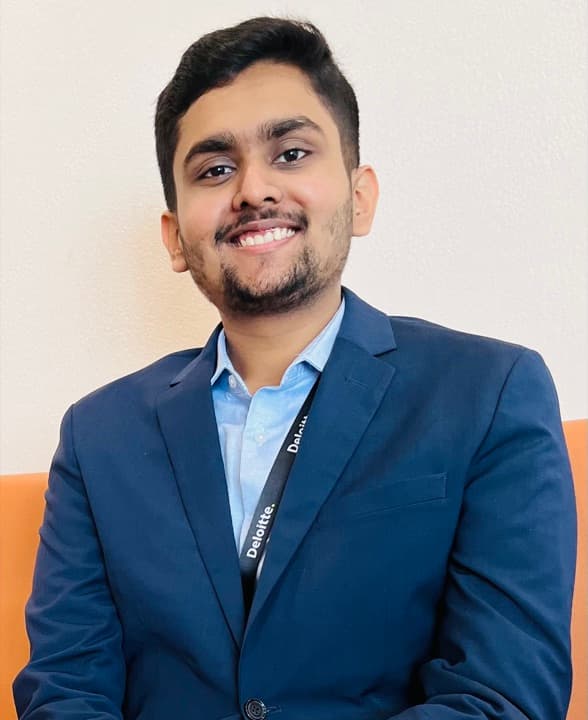
I'm Ritvik Chemudupati, an AI/ML infrastructure engineer who builds and runs production platforms end to end. For three years at Deloitte I built ML systems on AWS and Kubernetes, moving teams from experimental models to reliable, scalable deployments by designing distributed ML infrastructure, automating CI/CD pipelines, and operating GPU-accelerated workloads. Today I'm a Software and Systems Engineer at IT4Causes, leading email-security rollouts across nonprofit client tenants, and I ship my own products on GCP with Terraform, keyless CI/CD, and security-gated pipelines.

My work has helped reduce infrastructure costs by 20% (~$600K+ annually) while supporting 75+ data scientists across multiple teams and managing 4-8 production Kubernetes clusters. I'm passionate about bridging the gap between ML research and production systems.

Download Resume
Ritvik Chemudupati

Experience

Software and Systems Engineer

IT4Causes
Richmond, VA (Remote)
August 2026 - Present
MSP for 40+ nonprofitsGoogle Workspace + Microsoft 365200+ field deployment helper
  • •Lead deployment of INKY AI-powered email security across nonprofit client tenants on Google Workspace and Microsoft 365, taking each client from pilot testing through portfolio-wide rollout.
  • •Engineered a Chrome extension that streamlines a complete INKY deployment in the Google Admin console, covering 200+ fields across hosts, inbound gateway, and SMTP relay settings where one wrong checkbox can stop a client's mail.
  • •Deployed Kaseya 365 endpoint management with per-user configuration across the client portfolio, delivering every change through delegated access without direct admin rights.
  • •Represent IT4Causes in go-to-market and client conversations with nonprofits on email security, Microsoft 365/Azure, and AI adoption, owning client communication from scoping through rollout.
AI/ML Infrastructure Engineer

Deloitte
Hyderabad, India
July 2022 - July 2025
20% cost reduction~$600K annual savings75+ data scientists3 production teams
  • •Reduced Kubernetes infrastructure costs by 20% (~$600K annually) by consolidating from 7-8 to 3-4 clusters per account, rightsizing pods, tightening autoscaling bounds, culling idle notebooks, and removing orphaned EBS volumes and ECR images across multiple AWS accounts using AWS Cost Explorer.
  • •Deployed NVIDIA Morpheus on AWS EKS as sole owner of a production GPU inference platform serving 3 teams, configuring GPU scheduling with taints, tolerations, node selectors, IRSA for pod-level AWS credentials, and Lambda-to-EKS authentication through the aws-auth ConfigMap. Built Ansible automation for idempotent redeployment across clusters.
  • •Designed and operated end-to-end ML model serving infrastructure on Kubernetes, covering model packaging, inference service configuration on KServe, GPU resource allocation, and production rollout via GitOps, reducing deployment time for data science teams from days to hours.
  • •Built a self-service CI/CD platform for ML deployments on KServe, eliminating manual platform engineer involvement through GitHub OIDC federation with AWS for keyless ECR pushes and ArgoCD Image Updater for automatic rollouts. Scaled platform usage to 75+ data scientists across teams, surfacing VPC IP constraints at production-scale load.
  • •Operated Kubeflow on AWS EKS and helped recover a full production outage by manually reconstructing cluster state without terraform apply, restoring AZ-specific EBS volumes, creating AZ-targeted Kubernetes Jobs, and recovering data with Python-based S3 sync scripts.
  • •Provisioned EKS infrastructure using Terraform, including node groups, GPU p3/g5 and CPU m5 instance types, node labels for workload isolation, and staging/production cluster configuration.
  • •Deployed Robust Intelligence AI Firewall in a hybrid architecture, resolving production networking failures involving AWS hairpin NAT limitations, ALB annotations, and security group rules to connect the vendor control plane to on-cluster services.
  • •Implemented observability with Prometheus and Grafana across multiple Kubernetes clusters, building dashboards from pod logs and metrics for resource utilization and pipeline health.

Impact

20%
Cost Reduction
Infrastructure savings
$0K+
Annual Savings
Yearly cost optimization
0+
Data Scientists
Team members supported
4-8
K8s Clusters
Production clusters managed

Technical Skills

Languages

PythonPythonBashBashC++C++SQLSQL

Cloud Platforms

AWS EKSEKS
AWS EC2EC2
AWS S3S3
AWS IAMIAM
AWS LambdaLambda
AWS SageMakerSageMaker
AWS ECRECR
AzureAzure

Container Orchestration

KubernetesKubernetesDockerDockerHelmKnativeKnativeKustomizeKustomize

MLOps & ML Platforms

KubeflowKubeflowKServeKServeMLflowMLflowNVIDIA MorpheusNVIDIA MorpheusRobust IntelligenceRobust IntelligenceHopsworksHopsworksPyTorchPyTorch

CI/CD & GitOps

GitHub ActionsGitHub ActionsArgoCDArgoCDGitGit

Infrastructure as Code

TerraformTerraformAnsibleAnsible

Monitoring & Observability

PrometheusPrometheusGrafanaGrafanaCloudWatchCloudWatchKubecostKubecost

Certifications

NVIDIA

Getting Started with Deep Learning

NVIDIA

June 2025•Credential: M0S7oiZMQcO9R966P9O6-Q
NVIDIA

Fundamentals of Accelerated Data Science

NVIDIA

April 2025•Credential: P7Hq1rEUS6OwvnVGGaNDow

Education

Georgia Institute of Technology logo

Master of Science in Computer Science

Specialization: Artificial Intelligence

Georgia Institute of Technology

Atlanta, GA
2025 - 2026
Birla Institute of Technology and Science, Pilani logo

Bachelor of Engineering in Computer Science

Birla Institute of Technology and Science, Pilani

Hyderabad, India
2018 - 2022

Building ML platforms that have to stay up?

I'm open to AI/ML infrastructure and platform engineering roles. See what I've shipped since Deloitte, or reach out directly.